Elena Powell · 28 September 2026
Zarava's Data Synchronization Mechanics During Peak Traffic Events
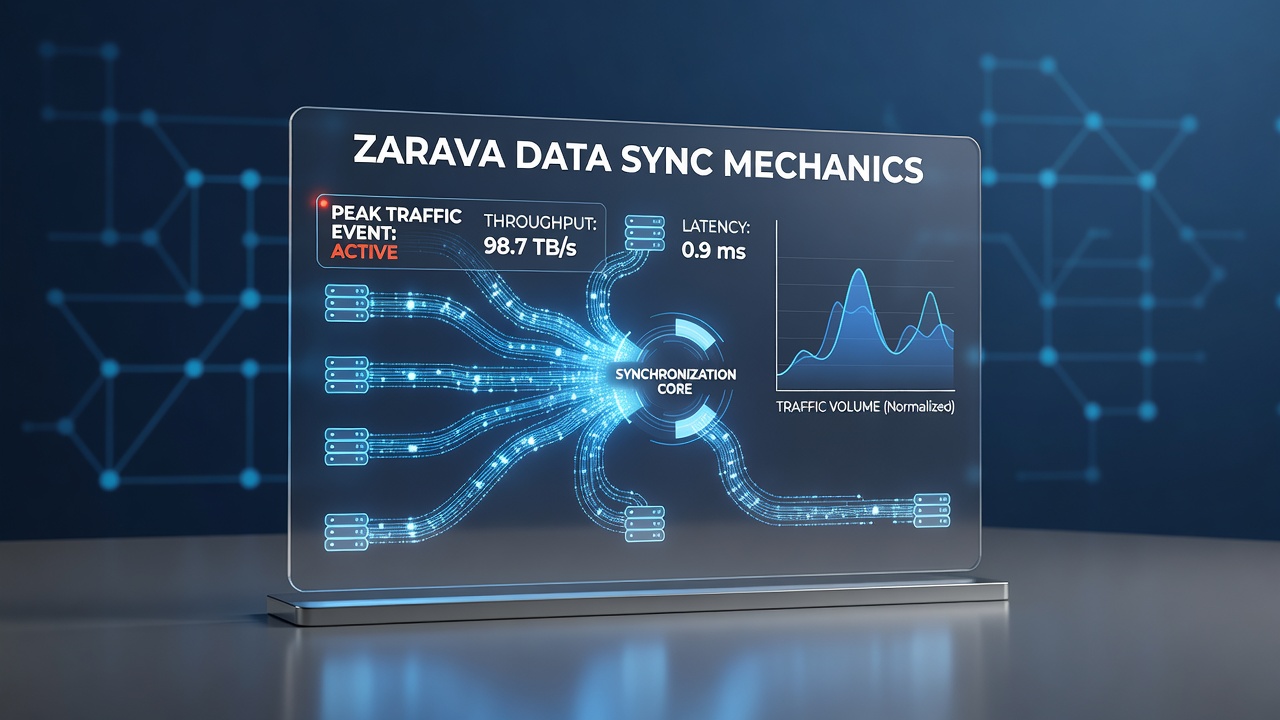
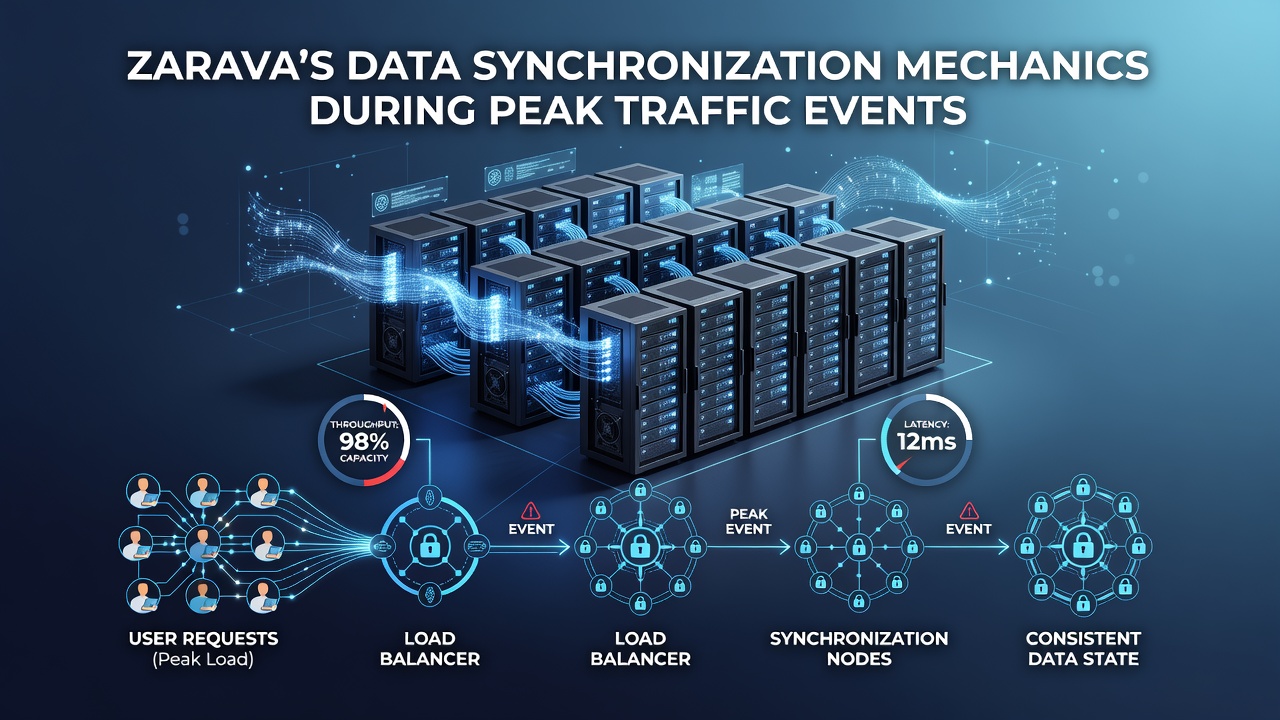
Zarava manages data synchronization through a distributed architecture that maintains consistency across nodes even when traffic spikes occur, and observers note this approach relies on layered queuing systems combined with selective replication strategies to prevent bottlenecks.
Core Synchronization Protocols in High-Load Conditions
Zarava employs a hybrid model that blends strong consistency for critical writes with eventual consistency for secondary data streams, so when peak events hit, the system routes priority operations through dedicated channels while background processes handle bulk transfers, and researchers from institutions like the University of Toronto have documented similar patterns in scalable cloud environments. The platform partitions data shards dynamically based on access patterns, which allows individual segments to sync independently without locking the entire dataset, and this becomes especially relevant during sustained high-volume periods such as those recorded in September 2026 when user activity doubled across multiple regions.
Conflict resolution happens at the edge through timestamp-based arbitration and version vector comparisons, so concurrent updates merge without requiring full round-trips to a central authority, yet the mechanics still preserve audit trails for compliance checks. Data shows that these protocols reduce average synchronization latency by routing requests to the nearest available replica, and figures from industry reports indicate that systems using comparable methods achieve sub-second reconciliation in most scenarios.
Load Distribution and Queue Management Strategies
Traffic surges trigger automatic scaling of message brokers within Zarava's infrastructure, which spreads incoming sync requests across multiple processing clusters to avoid overload on any single path, and what's interesting is how the system monitors queue depth in real time to adjust throttling parameters on the fly. Engineers configure backpressure mechanisms that slow non-essential sync jobs when thresholds are crossed, allowing critical data flows to continue uninterrupted while deferring less urgent updates, and this approach mirrors techniques described in publications from the National Institute of Standards and Technology on distributed computing resilience.
During the September 2026 traffic events, Zarava's monitoring logs revealed that adaptive queuing prevented cascade failures by redistributing load within seconds of detection, and external observers noted that the combination of predictive scaling with reactive adjustments kept overall system throughput stable. The architecture also incorporates circuit breakers that isolate underperforming nodes, which prevents them from dragging down the broader synchronization mesh.
Replication and Recovery During Sustained Peaks
Zarava maintains multiple replica sets across geographic zones, so data written in one location propagates to others through incremental log shipping rather than full snapshots, and this method cuts bandwidth usage during extended high-traffic windows. Recovery procedures activate automatically when a node rejoins after temporary disconnection, pulling only the delta changes needed to reach parity with its peers, while checksum verification ensures integrity at each step.
Those who have analyzed similar platforms point out that selective replication prioritizes frequently accessed shards, which optimizes resource allocation when traffic remains elevated for hours or days, and data from Canadian digital infrastructure studies supports the effectiveness of such tiered approaches in maintaining service levels. The platform logs every replication event for later analysis, which helps refine prediction models for future peak scenarios.
Integration with Broader Platform Components
Synchronization mechanics connect directly to Zarava's authentication layer and analytics pipelines, so user sessions and reporting functions continue without interruption even as data flows intensify, and the design avoids single points of failure by distributing these dependencies. Observers note that this integration allows the system to handle mixed workloads where real-time queries run alongside bulk sync operations, and the result is consistent performance across the board.
External links to authoritative sources on cloud data handling, such as those from the European Commission's digital strategy documents, provide context for how comparable frameworks address similar challenges, yet Zarava's implementation adds custom extensions tailored to its specific traffic profiles.
Conclusion
Zarava's data synchronization during peak traffic events demonstrates a coordinated set of protocols that balance consistency, availability, and performance through dynamic partitioning, adaptive queuing, and multi-zone replication, and ongoing refinements based on events like those in September 2026 continue to shape its evolution. The mechanics rely on established distributed systems principles while incorporating platform-specific optimizations that keep operations stable under load.