Elena Powell · 14 September 2026
The Role of Analytics in Optimizing Platform Performance After Major Updates
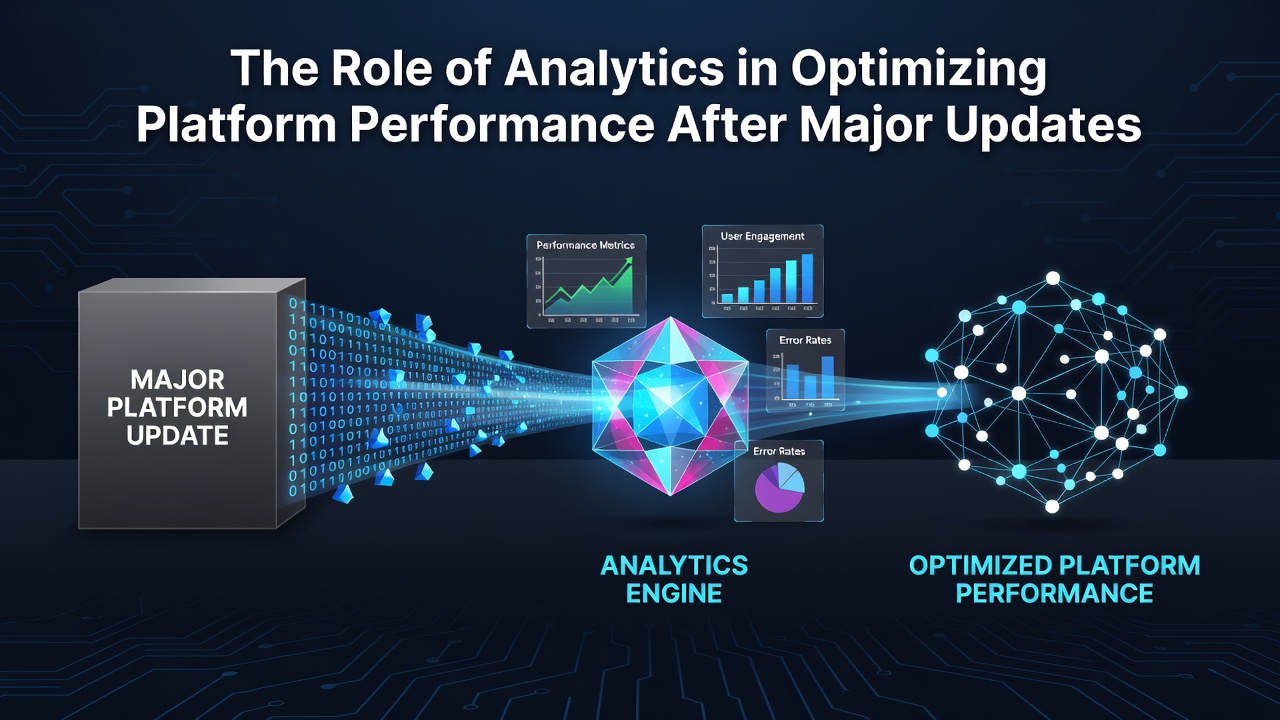
Major platform updates introduce new features, security patches, and architectural changes that can alter how systems handle traffic, process data, and deliver user experiences. Analytics track these shifts by collecting metrics on response times, error rates, and resource utilization right after deployment. In September 2026 several large SaaS providers rolled out infrastructure upgrades that affected latency across global regions, and teams relied on post-update data streams to identify bottlenecks within hours rather than days.
Core Metrics That Reveal Performance Shifts
Teams monitor uptime percentages, average page load durations, and server CPU utilization because these figures shift noticeably once code or database schemas change. User engagement indicators such as session length and conversion paths also move when navigation flows are modified, so analysts compare pre-update and post-update baselines side by side. Data from the Australian Bureau of Statistics on digital service adoption shows that platforms maintaining sub-two-second load times retain higher active user counts over successive quarters.
Crash frequency and API error codes surface immediately after updates when compatibility layers fail, while queue depth metrics highlight backend processing delays that users experience as sluggish responses. Observers note that combining these quantitative signals with qualitative feedback from support tickets produces a clearer picture of where optimization should begin.
Analytics Tools and Data Pipelines
Modern observability stacks aggregate logs from multiple sources into unified dashboards that update every few seconds. Custom scripts often pull information from application performance management systems and feed it into visualization layers that flag anomalies automatically. Researchers at academic institutions have documented how machine-learning models trained on historical update cycles predict which components are likely to degrade first.
Segmentation by geography, device type, and user cohort allows finer diagnosis because performance problems rarely affect every visitor equally. Real-time alerting thresholds trigger when metrics cross predefined limits, enabling engineers to roll back specific modules before widespread impact occurs. A report by the Pew Research Center on technology infrastructure trends indicates that organizations using automated threshold alerts reduced mean time to resolution by measurable margins during the 2025-2026 update wave.
Optimization Steps Guided by Data
Once analytics identify underperforming areas, teams prioritize fixes such as database indexing adjustments, content delivery network reconfiguration, or code-level caching improvements. A/B testing frameworks then compare modified versions against control groups to confirm gains before wider release. Those who have studied repeated update cycles know that iterative measurement prevents the common pattern of one fix creating another bottleneck elsewhere in the stack.
Resource allocation decisions also rest on analytics because capacity planning models incorporate traffic spikes observed during previous launches. When September 2026 updates coincided with seasonal shopping peaks, platforms that scaled servers according to predictive models maintained steadier performance than those relying on static estimates. External benchmarks from regulatory bodies in the European Union further support the practice of publishing transparency reports that include post-update performance summaries.
Long-Term Patterns and Continuous Monitoring
Analytics archives accumulate over multiple update cycles, revealing whether performance regressions recur in similar modules or whether certain architectural choices consistently deliver stability. Trend lines plotted across quarters show gradual drift that might otherwise go unnoticed until user complaints rise. Engineers use these archives to refine rollback procedures and to set more accurate expectations for future release schedules.
Cross-team reviews of the same datasets encourage alignment between product, infrastructure, and support groups because each perspective interprets the numbers differently. Shared dashboards reduce the time spent reconciling conflicting reports and keep focus on measurable outcomes rather than assumptions.
Conclusion
Analytics provide the factual foundation for diagnosing and correcting performance issues that emerge after major platform updates. By tracking defined metrics through integrated tools, applying data-driven fixes, and maintaining historical records, organizations sustain reliability even as systems evolve. Continued investment in these measurement practices supports consistent service quality across successive release cycles.